

Data quality metrics are measurable indicators that show how accurate, complete, consistent, and timely your data is. Every organization relies on data, from customer records to sales and operations. But if that data is inaccurate, outdated, or incomplete, it becomes a liability instead of an asset.
This guide explains what data quality metrics are, the 10 most useful ones with a formula and example for each, and how to put them to work.
What is data quality?
Data quality is how well data meets the requirements for its intended use, measured across dimensions such as accuracy, completeness, validity, uniqueness, consistency, and timeliness. High-quality data serves its purpose and supports sound decisions.
For example, high-quality data in a hospital means accurate, up-to-date patient records: demographics, medical history, diagnoses, treatments, and outcomes. Data quality teams measure each metric for those records and combine the results into an overall data quality score that shows whether the data can be trusted.
What are data quality metrics?
Data quality metrics are specific, objectively defined measurements that show whether a dataset is fit for purpose. As part of data quality management, they turn the condition of your data into numbers you can track, such as the percentage of incomplete records, the number of incorrect entries, or the share of duplicates.
Data quality dimensions vs. metrics vs. KPIs
These three terms are related but not interchangeable:
Dimension: the quality you care about, such as completeness or accuracy.
Metric: how you measure that dimension, such as complete records ÷ total records × 100.
KPI: the target you hold the metric to, such as "at least 97% of customer records complete each month."
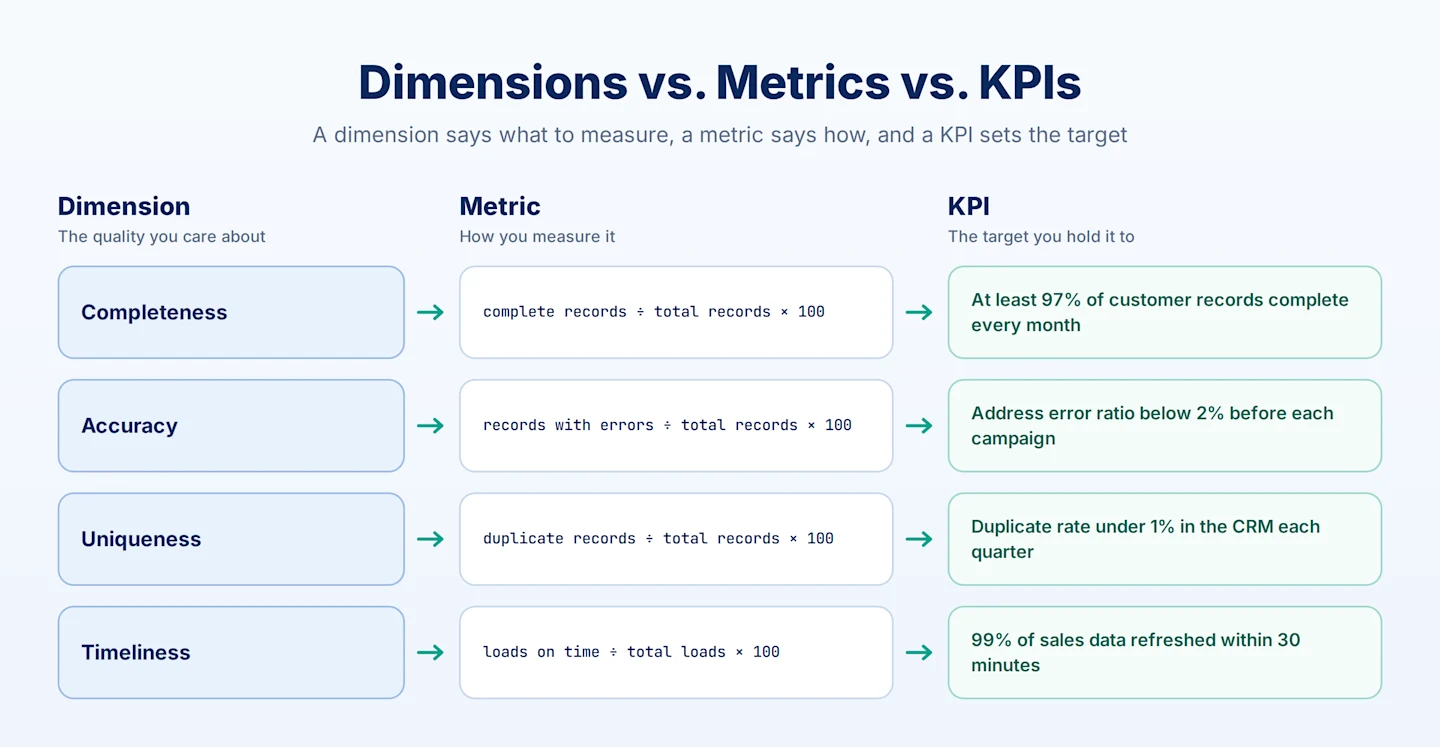
Researchers also group dimensions into four broad categories: intrinsic (credibility and objectivity), contextual (relevance, timeliness, and completeness), representational (format and presentation), and accessibility (how easy the data is to reach). These categories are a useful starting point for a data quality framework.
Why data quality metrics matter
Poor data quality has a direct cost. Gartner has estimated that poor data quality costs organizations an average of $12.9 million a year. Trust is still a problem, too. In the 2025 Outlook: Data Integrity Trends and Insights report from Precisely and Drexel University's LeBow College of Business:
67% of respondents said they don't completely trust the data they use for decisions.
64% named data quality as their top data integrity challenge.
77% rated their data quality as average or worse.
Data quality metrics quantify the current state of your data, so you can set targets, spot problems early, and show whether improvements are working.
Make Decisions Based on Data You Can Trust With Astera
Ensure your data's accuracy, completeness, and reliability using Astera's advanced profiling tools.

10 data quality metrics to track
The right metrics depend on your industry and how the data is used, but these 10 are widely used. The first six map to the core data quality dimensions. The last four track the health and cost of your data operations.
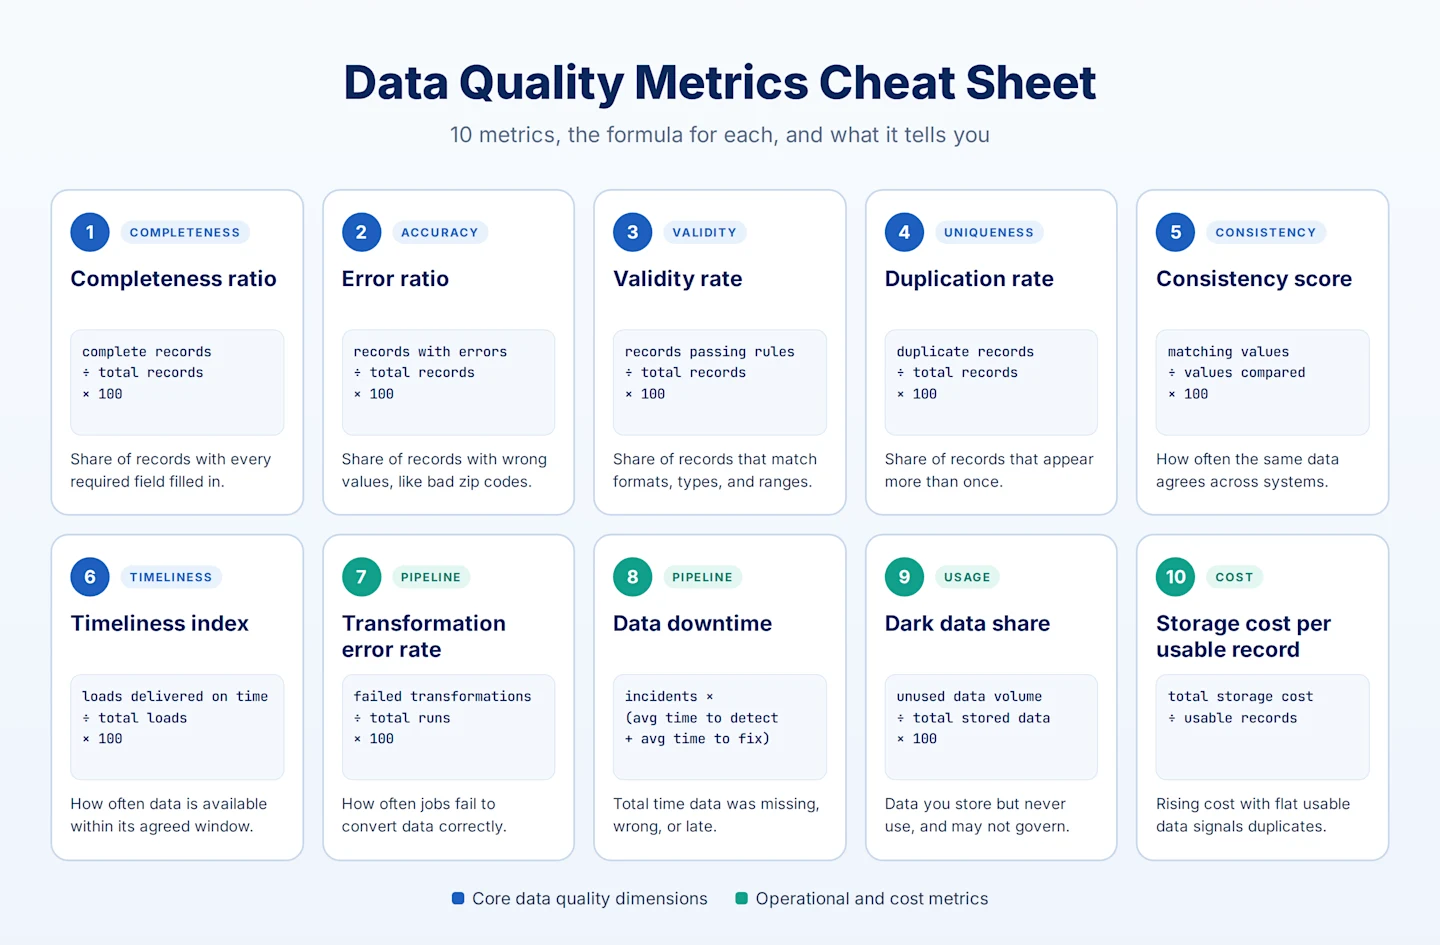
1. Completeness ratio
Dimension: Completeness
The completeness ratio measures how many records contain all the required data elements.
Formula: Completeness ratio = (complete records ÷ total records) × 100
Example: A customer table needs a name, address, email, and phone number for every customer. If 9,600 of 10,000 records have all four fields, the completeness ratio is 96%.
2. Error ratio
Dimension: Accuracy
The error ratio (or data-to-errors ratio) is the share of records that contain incorrect values. It shows where accuracy problems are concentrated.
Formula: Error ratio = (records with errors ÷ total records) × 100
Example: You have 1,000 addresses, and 100 contain wrong zip codes or misspelled city names. The error ratio is 100 ÷ 1,000 = 10%, so one in ten addresses is wrong.
3. Validity rate
Dimension: Validity
The validity rate is the share of records that pass your defined rules for format, data type, and allowed ranges. A value can be valid but still inaccurate, such as a correctly formatted email that belongs to someone else, so track it alongside the error ratio.
Formula: Validity rate = (records passing validation rules ÷ total records) × 100
Example: A rule requires dates in YYYY-MM-DD format and ages between 0 and 120. If 4,780 of 5,000 records pass, the validity rate is 95.6%.
4. Duplication rate
Dimension: Uniqueness
The duplication rate measures how many records appear more than once. Duplicates are common in customer data and inflate counts, costs, and outreach.
Formula: Duplication rate = (duplicate records ÷ total records) × 100
Example: A CRM has 20,000 contacts, and matching finds 640 duplicates. The duplication rate is 3.2%. Data scrubbing tools use exact and fuzzy matching to find and merge them.
5. Consistency score
Dimension: Consistency
The consistency score shows how often the same data agrees across systems, sources, and time periods. Robust data integration helps remove inconsistencies between systems.
Formula: Consistency score = (matching values ÷ total values compared) × 100
Example: You compare customer status in the CRM and the billing system for 8,000 customers. If 7,840 match, the consistency score is 98%.
6. Timeliness index
Dimension: Timeliness
The timeliness index measures whether data is available when it's needed. You can track it as the delay between an event and its data being available, or as the share of loads delivered within an agreed window (SLA).
Formula: Timeliness index = (loads delivered on time ÷ total loads) × 100
Example: Sales data should refresh every 30 minutes. If 1,428 of 1,440 loads in a month arrive on time, the timeliness index is 99.2%.
7. Data transformation error rate
Dimension: Pipeline health
This metric tracks how often transformation jobs fail or produce bad output, for example because of unexpected formats or schema changes. A rising rate often points to upstream quality problems.
Formula: Transformation error rate = (failed transformation runs ÷ total runs) × 100
Example: Out of 2,000 nightly transformation runs in a quarter, 30 fail. The transformation error rate is 1.5%.
8. Data downtime
Dimension: Pipeline health
Data downtime is the total time data was missing, wrong, or late. It combines how often incidents happen with how long they take to detect and fix.
Formula: Data downtime = number of incidents × (average time to detect + average time to resolve)
Example: Six incidents in a month, each taking 2 hours to detect and 4 hours to fix, add up to 6 × (2 + 4) = 36 hours of data downtime. Data observability tools help reduce it.
9. Amount of dark data
Dimension: Usage
Dark data is data an organization collects and stores but never uses. It isn't automatically poor quality, but it often contains outdated or inaccurate information and unprotected sensitive data that raises breach risk.
Formula: Dark data share = (unused data volume ÷ total stored data) × 100
Example: If 40 TB of 100 TB stored has not been queried in a year, 40% of your data is dark and worth reviewing, archiving, or deleting.
10. Data storage costs
Dimension: Cost
When storage costs keep rising but the amount of usable data stays flat, redundancy and duplication are usually the cause. Poor-quality data also makes backup and recovery harder. Track cost against usable data, not on its own.
Formula: Storage cost per usable record = total storage cost ÷ usable records
Example: If monthly storage costs rise 20% while usable records grow only 2%, check for duplicates and redundant copies.
How to measure data quality
Use these steps to turn the metrics above into a working measurement process:
Pick the data that matters most. Start with the datasets behind key reports, customer operations, or AI models.
Choose dimensions and metrics. Select the few dimensions that matter most for each dataset, then the metric for each.
Profile the data to set a baseline. Data profiling tools show current completeness, error, and duplicate levels.
Set targets (KPIs). Base them on business needs and industry standards, for example "no more than 3% incomplete customer records."
Automate checks. Build data validation and data quality rules into your pipelines so metrics update on every run.
Report and act. Share a data quality scorecard with data owners, and fix root causes when a metric misses its target.
Best practices for using data quality metrics
There's no one-size-fits-all set of metrics. They depend on your business goals, data sources, and the regulations you follow.
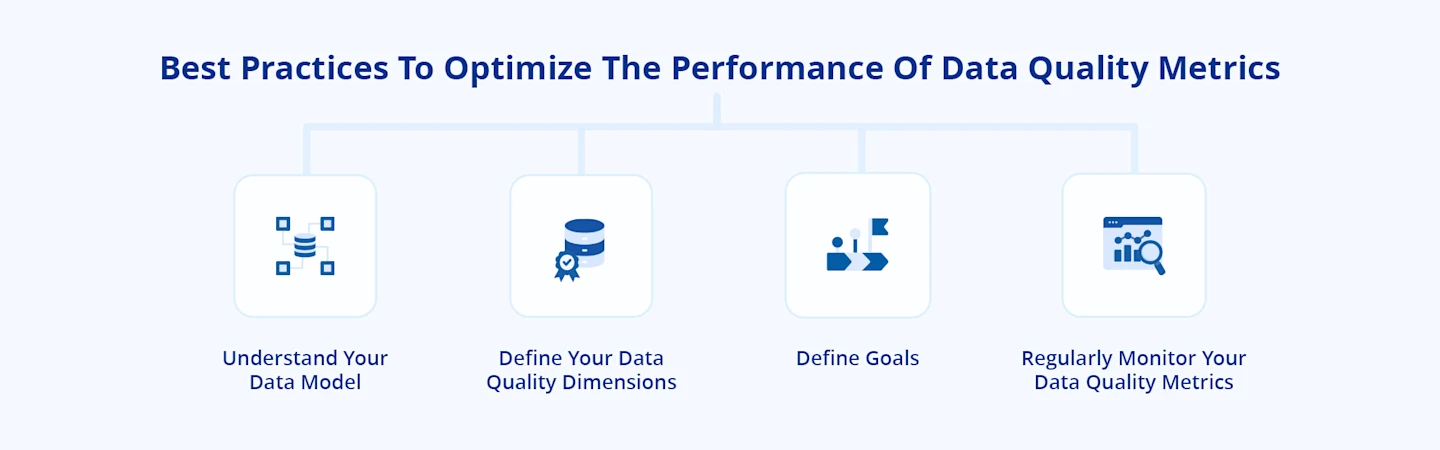
Understand your content requirements and data model
Know what your data should look like and how it should behave (your content requirements), and how it's structured and related (your data model). This keeps your metrics tailored to how your data is actually organized.
Prioritize the right dimensions
Focus on the dimensions that matter most for each use case. For financial transactions, accuracy and consistency come first. For a marketing campaign, completeness and relevance of customer data matter more.
Set clear, realistic goals
Targets tie metrics to outcomes. For example, keeping incomplete customer records under 3% sets a clear expectation and links it to a better shopping experience. Documenting use cases also helps teams see how data quality supports business goals.
Monitor metrics regularly
Track metrics continuously and investigate when one misses its target. If missing values rise above 3%, look first at specific causes such as data entry errors or a broken collection method, before rethinking your wider data management strategy.
Track data quality metrics with Astera Data Pipeline
Data quality metrics give you a clear, quantifiable way to assess and improve data accuracy, consistency, and reliability. The right tool makes them easier to measure and act on.
Astera Data Pipeline is an AI-powered, no-code platform with automated data cleansing transformations, customizable data quality rules, and built-in data profiling and validation. Its Data Quality Mode captures statistics on every run, so you can monitor quality as data moves. To compare options, see our list of the best data quality tools.
Start a 14-day free trial to see how Astera Data Pipeline improves your data quality.
Turn Data Quality from Cost Center to Competitive Advantage
Eliminate the millions of dollars incurred annually due to poor data quality. See how automated profiling and validation ensure every dataset meets AI-ready standards before training begins.